Six of Every Ten Export Dollars Korea Earned in August Were Tech

If you want to know whether the AI buildout is real, look at what leaves Busan. Record
South Korea chip exports helped push the country’s technology shipments to $59.98 billion in
August 2026. The figure comes from a joint report by the Ministry of Science and ICT and the Ministry of
Trade, Industry and Energy, released on 14 September. Information and communications technology passed 60
per cent of total exports for the first time.

What South Korea chip exports actually recorded

Semiconductors did most of the work. Chip shipments rose 209 per cent year on year to $46.67 billion.
Computers and communications equipment climbed 383.1 per cent to $6.4 billion.

Total ICT exports of $59.98 billion compare with $22.84 billion in August 2025, a rise of 162.6 per cent.
The sector posted a trade surplus of $41.37 billion, also a record.

Those growth rates are extraordinary by any normal reading of trade data. They come from the ministries’
own release, and they reflect both volume and price. High-bandwidth memory used in AI accelerators carries a
far higher unit value than the commodity memory that dominated earlier cycles.
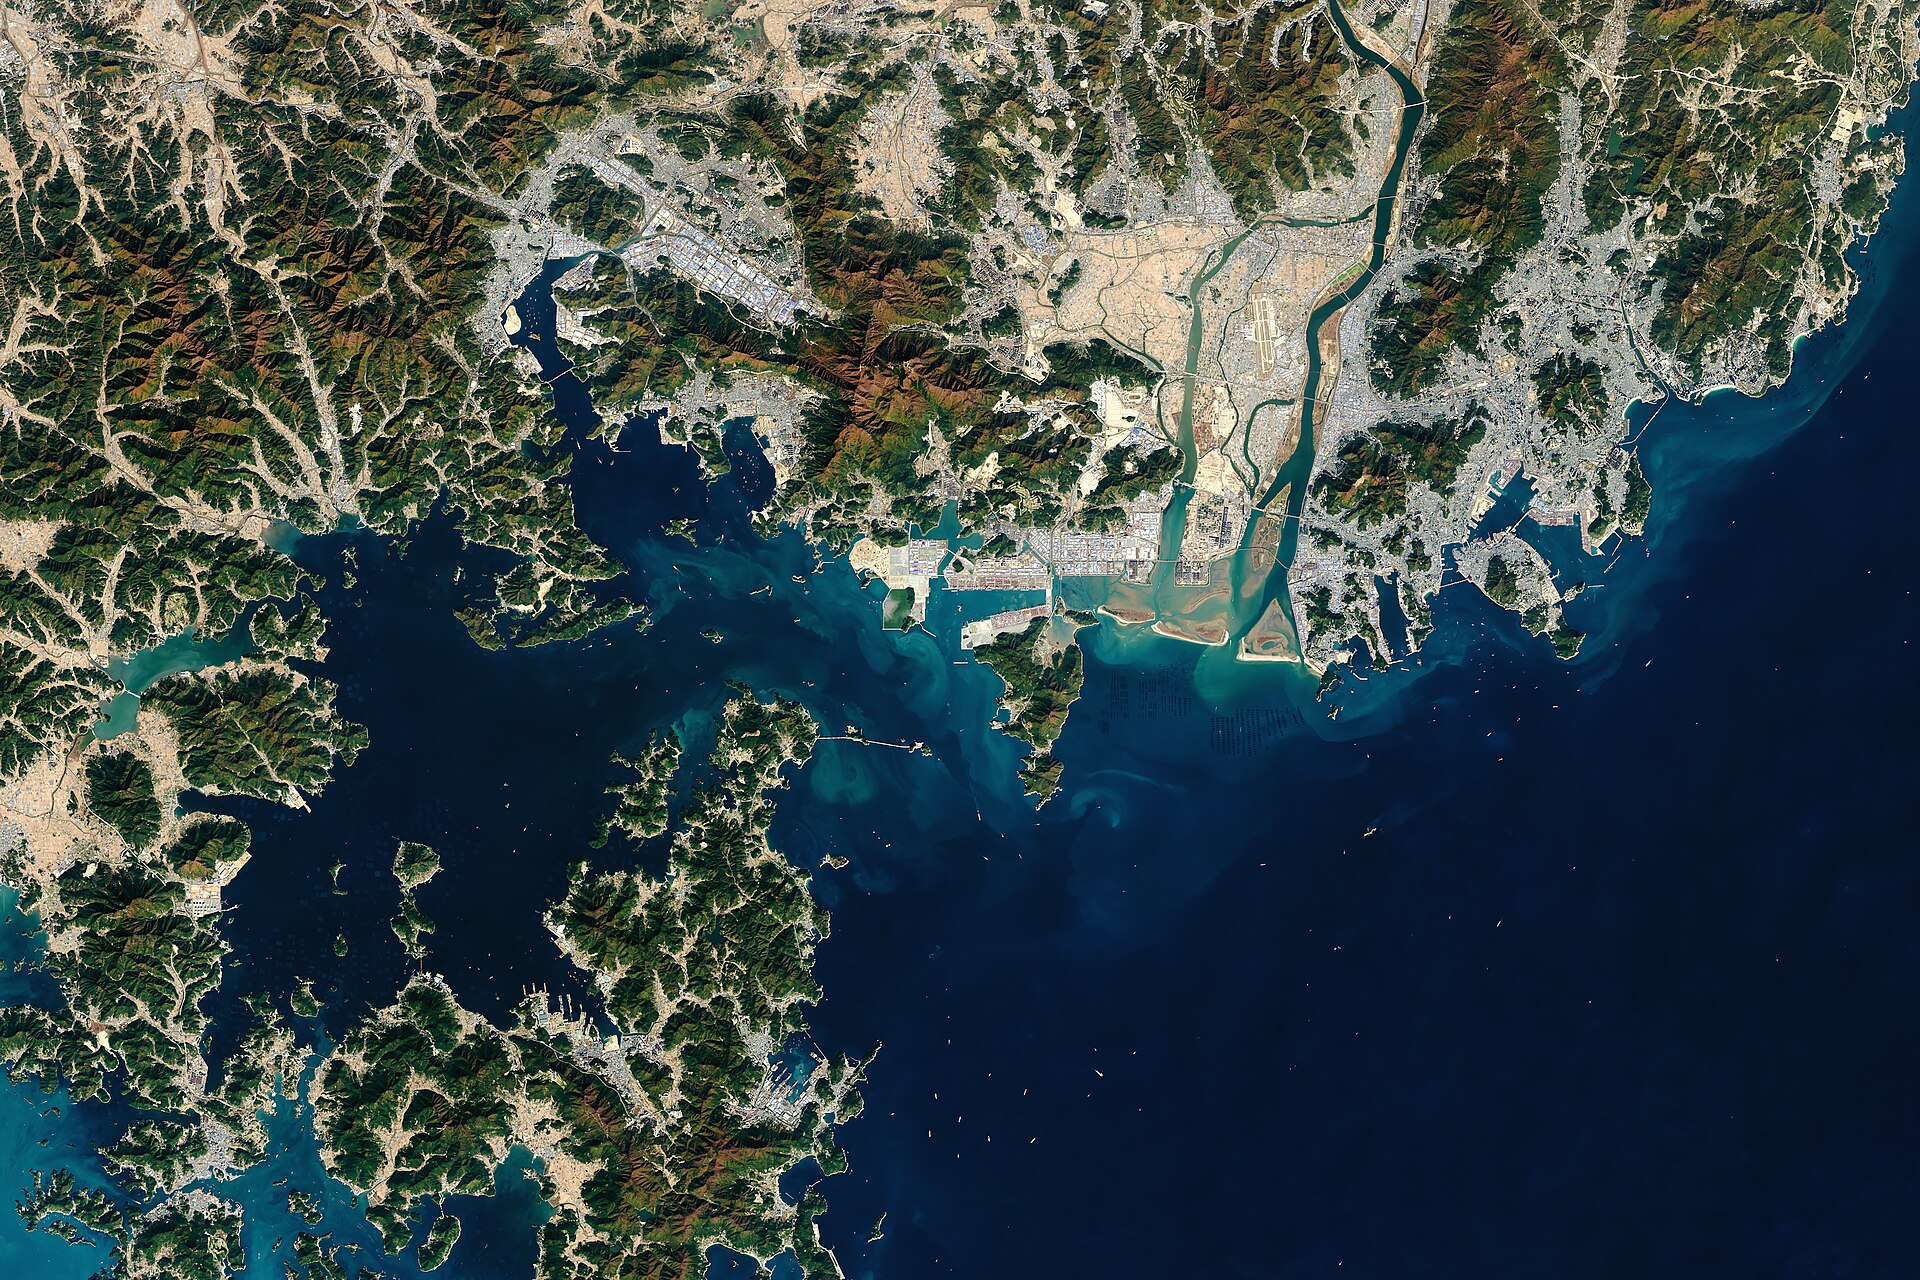
Satellite view of Busan container port, the gateway for South Korea chip exports
Busan container port from orbit. Korean memory and logic chips move through terminals like this one.

Why Korea is the cleanest read on AI demand

Samsung Electronics and SK hynix supply much of the world’s advanced memory, including the high-bandwidth
memory that AI accelerators require. Without it, a GPU cannot be assembled into a working system.

That gives Korean customs data an unusual property. It measures hardware actually shipped, not hardware
announced. Capital-expenditure plans can be revised quietly. Export tonnage cannot.

Demand spread widely by destination. Shipments to the United States rose more than 300 per cent.
Exports to China and Hong Kong, Vietnam, the European Union and India all rose sharply as well.

The breadth is the useful signal. A surge to one destination can mean a single customer stockpiling.
Growth across the United States, China, Vietnam, Europe and India at once points to broad build-out rather
than one buyer’s inventory decision.

Vietnam deserves a note of its own. Much of what ships there goes for assembly and test before moving on
again. Its numbers partly measure the same demand a second time, further along the chain.

The concentration underneath the record

A sector at more than 60 per cent of national exports is a strength and an exposure at the same time.
Reporting on the release noted that stripping ICT out would leave the country running a trade deficit of
about $6.6 billion for the month.

That is the risk in one number. Korea’s external accounts now depend heavily on one demand cycle in one
industry.

The timing sharpens it. These figures landed the same week AI lab chiefs called publicly for slower
frontier-model development, and chip stocks fell across three continents. Our reports on
that slowdown call and
on the Qualcomm-Amazon AI chip
deal
cover the demand side of the same market. Korea’s own policy response runs through skilled
migration too, as our piece on
China’s competing
computing plan
shows for the region.

What the record changes for the rest of the market

For buyers, sustained Korean output eases the memory shortage that has constrained accelerator supply.
For competitors, it raises the bar: matching this volume takes fabs that take years to build.

For policymakers elsewhere, the data is an argument in ongoing subsidy debates. Countries funding
domestic semiconductor capacity will cite these figures in both directions — as proof the market is worth
entering, and as proof of how far ahead the incumbents already are.

Whether the numbers hold

Three things decide that. The first is whether AI capital spending continues at its current pace into
2027. The second is memory pricing, which has driven much of the value growth and can fall quickly. The
third is export-control policy, which shapes where Korean fabs can sell and what equipment they can buy.

September data, due in mid-October, is the next check. A single record month proves a peak. Two
consecutive ones start to prove a trend.

Export data questions

How large were the exports?

ICT exports reached $59.98 billion in August 2026, up 162.6 per cent from $22.84 billion a year earlier.

How much of that was semiconductors?

Chip exports were $46.67 billion, a rise of 209 per cent year on year.

Who published the figures?

The Ministry of Science and ICT with the Ministry of Trade, Industry and Energy, in a report released on 14 September 2026.

What share of total exports is ICT now?

More than 60 per cent, the first time the sector has passed that threshold.

Why do these figures matter for AI?

Samsung and SK hynix supply much of the high-bandwidth memory AI accelerators need, so Korean shipments track real hardware demand.

What is the risk in the record?

Concentration. Reporting on the release noted that without ICT, Korea would have run a monthly trade deficit of about $6.6 billion.

Citations

An AI Lab Just Quit Big Tech’s Lobby Over Three Bills on Chips

An AI company has walked out of Washington’s biggest tech trade group over three
chip export bills. Anthropic is ending its membership of the Information Technology
Industry Council, Axios reported on 8 September 2026. ITI had written to the Senate and House Armed Services
Committees urging lawmakers to strip the AI OVERWATCH Act, the Chip Security Act and the MATCH Act from this
year’s defence policy bill. Anthropic supports all three.

What the three chip export bills would do

Each measure attacks a different gap in the current export-control regime.

The AI OVERWATCH Act would require the Commerce Department to notify Congress before approving export
licences for sensitive dual-use chips destined for adversarial nations, and to allow a review period first.
That review window was shortened from two years to 18 months. ITI described 18 months as “an eternity”.

The Chip Security Act would require companies to track their AI chips, aimed at countering smuggling of
US technology. The MATCH Act would press American allies to restrict sales of chipmaking equipment to China,
slowing the growth of its domestic industry.

All three cleared the House Foreign Affairs Committee with substantial bipartisan support. They sit in
the Senate National Defense Authorization Act managers’ package, following technical assistance from the
White House.

An AI processor die, the technology behind the chip export bills split
An AI processor die. Tracking requirements in the Chip Security Act would follow hardware like this after export.

Why Anthropic broke with the group over the chip export bills

ITI’s letter argued the measures would damage American dominance in global markets. Its membership
includes Google, OpenAI and Nvidia — companies with large commercial stakes in international chip and model
sales.

An ITI spokesperson confirmed the departure, describing a “broad consensus position” among members that
the three bills should not advance in the NDAA. The spokesperson said the membership is aligned that the
bills undermine the American tech stack. Both sides here are stating their own case, and each has a
commercial interest in the outcome.

Anthropic’s position runs the other way. Chief executive Dario Amodei has argued publicly for tighter
restrictions on advanced chip exports to China. Supporters of the bills say they give existing controls the
durability they currently lack, since administrative rules can be rewritten by the next administration.

A pattern of breaking from the industry line

This is not the company’s first split from its peers. Anthropic has diverged from OpenAI and Google on
state AI safety legislation. It was also the only major lab not to directly sign a July 2026 letter
supporting open-weight models.

Trade associations work by aggregating members into a single position. That works while members share
interests. It breaks when one member’s strategy depends on rules the others are lobbying against.

The politics do not split cleanly along party lines either. Conservative groups including Heritage Action
and American Compass back the bills, alongside bipartisan congressional support. We covered the broader
safety argument inside the industry in our report on
the AI development slowdown
its own builders are asking for
, and the competitive backdrop in
China’s intelligent
computing plan
.

What the fight means outside Washington

For chipmakers, the Chip Security Act’s tracking requirement is the operational question. Following
hardware after sale means new record-keeping obligations across distributors and resellers.

For allied governments, the MATCH Act is the sensitive one. It asks other countries to restrict their own
equipment exports, which raises sovereignty objections in the Netherlands, Japan and South Korea. Our report
on the Nvidia-Groq antitrust
probe
covers the regulatory pressure building on the same companies from a different direction.

For buyers outside the United States, more licensing steps usually mean longer lead times, even where a
licence is eventually granted.

The NDAA clock now running

The Senate returned from summer recess on 14 September with the NDAA awaiting floor action. That is where
the three measures live or die.

Three signals will show which way it goes. Whether the bills survive the managers’ package intact. Whether
the 18-month review period gets stretched or trimmed in negotiation. And whether other ITI members follow
Anthropic out, which would say more about the association’s future than about the bills.

Questions about the split

Which three bills are involved?

The AI OVERWATCH Act, the Chip Security Act and the MATCH Act, all attached to this year’s National Defense Authorization Act.

Why did Anthropic leave ITI?

ITI wrote to congressional committees urging that the three bills be stripped from the defence bill. Anthropic supports them.

What does the Chip Security Act require?

It would require companies to track their AI chips, aimed at countering smuggling of US technology.

What is the MATCH Act?

A measure pushing US allies to restrict sales of chipmaking equipment to China, to slow its domestic chip industry.

Who else belongs to ITI?

Members include Google, OpenAI and Nvidia. An ITI spokesperson described a broad consensus among members against the three bills.

When will this be decided?

The Senate returned on 14 September with the NDAA awaiting floor action, so the outcome turns on that legislative process.

Reporting used

China Intelligent Computing Plan Targets 9,800 EFLOPS by 2030

China’s Ministry of Industry and Information Technology has published a five-year blueprint that puts a number on the country’s AI ambitions. The China intelligent computing plan, set out in the 15th Five-Year Plan for the information and communications industry released on 7 September 2026, targets 9,800 exaflops of intelligent computing capacity by 2030 — roughly six times the 1,590 exaflops baseline it cites for 2025 — supported by 3.8 trillion yuan of cumulative information infrastructure investment over the period.

Reading the target honestly

These are the Chinese government’s own targets, published by the ministry that will be judged against them, and Chinese five-year plans have a mixed record of delivery. They are still worth reading, because they reveal what the state has decided to spend on and how it defines success.

Two features stand out. First, the metric is compute capacity rather than model capability — the plan commits to building the substrate, not to producing a particular system. Second, the scale of the increase is front-loaded on infrastructure: reporting on the plan pairs the 9,800 exaflops figure with the 3.8 trillion yuan investment envelope, which is on the order of $530bn at recent exchange rates.

A note on units, because the figures get quoted loosely. Intelligent computing capacity as Chinese planners define it is measured at lower numerical precision than the FP64 benchmarks used for traditional supercomputer rankings. It is not directly comparable to the top of the TOP500 list, and anyone treating the two as equivalent is comparing different things.

The constraint the plan is built around

US export controls have, since 2022, progressively restricted Chinese access to the highest-performing AI accelerators and, increasingly, to the equipment used to make them. A national compute plan drafted in 2026 therefore cannot assume access to Nvidia’s leading parts, or AMD’s, or Intel’s.

The plan is explicit about building on domestic supply. That has a practical consequence that is easy to miss: hitting a capacity target with less capable individual chips means using far more of them, which raises the bill for power, cooling, floor space and interconnect. Reporting by DigiTimes points to ambitions around very large clusters — in the range of 100,000 accelerator cards — which is consistent with that arithmetic. Energy, not silicon, becomes the binding constraint at that scale.

It also means the plan is a demand signal to China’s domestic chipmakers, foundries and equipment vendors as much as it is a compute target. Guaranteed state-backed demand is how you finance a supply chain that cannot yet compete on unit economics.

The software half of the strategy

Alongside the infrastructure plan, the ministry issued an implementation plan for an “Artificial Intelligence Plus Software” action, reported in the days that followed. Its stated aims include optimising intelligent programming toolchains, pushing enterprises toward technical transformation measured on code quality and R&D productivity, and embedding automated security testing across the software development lifecycle — with an ambition to take Chinese professional software to world markets by 2030.

The through-line is import substitution applied one layer up the stack. Compute is the expensive part, but design and development tools are the part where dependency is hardest to unwind, because it is embedded in engineers’ habits and in decades of existing designs. China’s broader innovation agenda for the 2026 to 2030 period has been outlined in similar terms by the science and technology ministry, whose plans were published on the State Council’s English portal.

What this changes outside China

For chipmakers outside China, the plan confirms what export controls already implied: the Chinese AI-accelerator market is closing as an addressable opportunity, and the competitive question shifts to third markets. For Western AI labs, a compute build-out of this scale narrows the assumption that access to frontier compute is a durable moat.

For energy markets, it is another large data-centre demand curve landing on a grid that has to be planned years in advance — the same pressure visible in Europe and North America, at a different scale and with different politics.

What to watch through 2027: whether reported capacity additions track the trajectory implied by a 2030 target, how much of the build uses domestic accelerators versus stockpiled or grey-market foreign parts, and whether power availability starts appearing as the published constraint rather than chips.

Questions

What does the China intelligent computing plan target?

9,800 exaflops of intelligent computing capacity by 2030, up from a stated 2025 baseline of 1,590 exaflops, backed by 3.8 trillion yuan of cumulative information infrastructure investment.

Who published it and when?

The Ministry of Industry and Information Technology, through its information and communications development department, published the 15th Five-Year Plan for the industry on 7 September 2026.

Is that comparable to supercomputer rankings?

No. Intelligent computing capacity is measured at lower numerical precision than the FP64 benchmarks used in traditional supercomputer lists, so the figures are not directly comparable.

Does the plan rely on Nvidia chips?

No. It is built around domestic supply, reflecting US export controls that restrict Chinese access to leading foreign AI accelerators and manufacturing equipment.

What is the AI Plus Software action?

A separate implementation plan from the same ministry covering intelligent programming toolchains, enterprise technical transformation and automated security testing, with an aim of exporting Chinese professional software by 2030.

Should these targets be treated as forecasts?

They are government objectives published by the ministry responsible for meeting them, not independent projections, and should be read with that interest in mind.

Positron AI Funding Round Bets $875M Against the HBM Shortage

Positron AI has closed an $875 million Series C at a $5 billion post-money valuation, and the Positron AI funding round is a bet on a specific contrarian idea: that the memory bottleneck in AI inference can be solved with cheap commodity chips instead of the scarce, expensive high-bandwidth memory everyone else is fighting over.

The company announced the raise in two tranches: $375 million in the Series C proper, and a Series C-1 of up to $500 million.

The bet: skip HBM entirely

Inference workloads are memory-hungry. Serving a large model means holding enormous weights close enough to the compute to be read fast, which is why high-bandwidth memory has become the industry’s tightest constraint — supply is limited, advanced packaging capacity is limited, and Nvidia absorbs much of both.

Positron’s next-generation chip, Asimov, pairs its compute architecture with 288GB to 2,304GB of LPDDR5X per chip. LPDDR5X is commodity memory, the kind that goes into phones and laptops. It is slower per bit than HBM and vastly more available.

The wager is that for inference specifically, capacity beats peak bandwidth — that fitting more of the model in memory matters more than reading any single part of it at maximum speed. If that holds, Positron sidesteps the supply chain that constrains its competitors.

It is an engineering claim, not yet a proven one, and the company is the party asserting it.

Who wrote the cheques

The round was co-led by NEA, Atreides Management, Valor Equity Partners, Andra Capital, Dylan Patel’s SemiAnalysis Capital, and Jim Clark — the founder of Silicon Graphics and Netscape.

Additional investors include the Qatar Investment Authority, DFJ Growth, Cisco Investments, Hudson River Trading and Naver Ventures, alongside existing backers.

Two names stand out for what they signal. SemiAnalysis Capital is the investment arm attached to a research operation that scrutinises exactly this kind of architectural claim, which makes its participation a form of technical endorsement. Hudson River Trading is a high-frequency trading firm — a buyer whose entire business depends on inference latency, not a generalist fund.

Where the money goes

Per the company, the financing funds three things: the Asimov tapeout; a 2MW-plus engineering data centre and emulation platform; and the production ramp of Titan, its current-generation inference system, including LPDDR5X supply commitments and go-to-market expansion.

Asimov is scheduled to tape out on TSMC’s N3P process at the end of 2026, with production targeted for the second half of 2027, as SiliconANGLE reported.

That timeline is the thing to hold onto. Silicon announced in 2026 for production in late 2027 has roughly eighteen months of execution risk ahead of it, in a market where the competitive baseline moves every quarter.

Titan is what bridges the gap. It is the current-generation system, shipping now, and the LPDDR5X supply commitments funded by this round are as much about securing memory allocation for that ramp as about the future chip. Commodity memory is abundant relative to HBM, but “abundant” is not the same as “available at volume on contract”, and locking supply early is how a company avoids becoming the constraint it was designed to escape.

The competitive picture it enters

Inference silicon has become the most contested corner of the AI hardware market, because it is where the recurring revenue is — training happens in bursts, inference runs continuously.

The incumbents are not standing still. Qualcomm committed to a large-scale inference partnership with Amazon, covered in our report on that deal, and Nvidia’s manoeuvring in the space has drawn antitrust attention, as we set out in the DOJ’s look at the Groq arrangement.

A $5 billion valuation for a company whose flagship product ships in eighteen months prices in a lot of confidence. The structure of the raise — a second tranche of “up to” $500 million — suggests the investors built themselves some optionality about how much of that confidence to fund immediately.

The question that decides it

Whether commodity memory is genuinely good enough for production inference at scale, or good enough only for workloads where latency tolerance is generous.

Positron says the former. Its customers will establish which is true, and the evidence arrives in 2027. Until then, the round is a well-capitalised hypothesis.

Questions about the raise

How much did Positron raise and at what valuation?

$875 million total at a $5 billion post-money valuation, split into a $375 million Series C and a Series C-1 of up to $500 million.

What is different about the Asimov chip?

It uses commodity LPDDR5X memory — 288GB to 2,304GB per chip — rather than high-bandwidth memory, avoiding the HBM and advanced packaging supply constraints that limit competing inference hardware.

When will Asimov be available?

It is scheduled to tape out on TSMC’s N3P process at the end of 2026, with production targeted for the second half of 2027.

Who led the round?

Co-leads were NEA, Atreides Management, Valor Equity Partners, Andra Capital, SemiAnalysis Capital and Jim Clark. Other investors include the Qatar Investment Authority, Cisco Investments and Hudson River Trading.

Is Positron competing directly with Nvidia?

In inference, yes. It is not targeting training workloads, where Nvidia’s position is strongest.

What is the main risk?

Execution and timing. The flagship chip is roughly eighteen months from production in a market where competing hardware advances continuously, and the performance claim for commodity memory is not yet demonstrated at scale.

More on the inference hardware race in our coverage of the Qualcomm-Amazon agreement and Google’s European data centre build-out.

The Real AI Chip Bottleneck Isn’t the Chip — It’s the Wires

The AI chip interconnect bottleneck took center stage as SEMICON Taiwan 2026 opened in Taipei on 31 August. The event drew more than 100,000 semiconductor professionals from 65 countries to International Semiconductor Week. SEMI’s Terry Tsao delivered the conference’s central message, and it was blunt. Moving data between AI chips can now consume more energy than the computation itself. That shifts the industry’s hardest problem from individual chip performance to system-level architecture.

Why the AI chip interconnect bottleneck changes the conversation

For years, chipmakers competed primarily on transistor density and raw compute throughput. SEMICON Taiwan’s 2026 agenda reflects a shift toward a different metric entirely. The new focus is how efficiently data moves between thousands of chips working together inside a single AI training cluster. AI models have grown, and so has the number of chips that must communicate constantly during training. The wiring and interconnect standards linking them have not kept pace with compute gains. That gap creates exactly the kind of bottleneck Tsao described.

AI chip interconnect bottleneck

Who is racing to solve the wiring problem

Nvidia has staked much of its roadmap on faster interconnect standards to keep pace with the chips it sells. Its GPU Technology Conference earlier this year saw Jensen Huang announce roughly $1 trillion in expected orders for its Blackwell and Vera Rubin chip generations through 2027. Those orders depend partly on solving the same data-movement problem SEMICON Taiwan highlighted. Component suppliers focused on optical and copper interconnect technology have seen renewed investor interest as a result. Faster, more energy-efficient connections between chips could unlock compute gains that raw chip design alone cannot deliver.

The regulatory backdrop shaping who can compete

The interconnect race is unfolding alongside tightening US export controls on advanced AI chips and the semiconductors that power them. The Commerce Department has signaled further regulatory action on chips and AI is coming. The Department has separately signed letters of intent worth $874 million with seven companies to strengthen the domestic compute supply chain. Those two threads are tighter export rules abroad and new incentives at home. Together they are pushing US-based chip and interconnect makers to treat domestic manufacturing capacity as a competitive necessity, not a cost center.

Taiwan’s own chipmakers face a delicate balance in this environment. They supply both US and Chinese customers. Interconnect standards adopted at events like SEMICON Taiwan increasingly carry geopolitical weight alongside their technical merits. TSMC and other Taiwanese suppliers have avoided taking public positions on which standard should win out. They prefer to support multiple approaches until the market settles on a default, a stance that lets them keep selling into both American and Chinese supply chains without picking a side.

How this affects AI training timelines industry-wide

Data-center operators say interconnect limits already stretch some training runs longer than the chips themselves would require. A cluster with thousands of top-tier chips gains little if those chips spend significant time waiting on data transfers rather than computing. That waiting time translates directly into higher costs. Labs still pay for chip time regardless of utilization. Several cloud providers have begun advertising interconnect specifications alongside raw chip counts for the first time this year. Industry analysts say the shift reflects customer demand for clearer efficiency metrics. Buyers increasingly ask about bandwidth between chips before they ask about raw chip counts, according to several vendors present at the conference.

Smaller AI labs without the scale to negotiate custom interconnect solutions face a particular disadvantage. They typically rely on off-the-shelf networking gear that larger labs have already moved past. That gap can leave them paying similar chip costs for meaningfully worse effective performance. Several smaller labs have started pooling compute purchases specifically to negotiate better interconnect terms, mimicking a strategy large cloud providers pioneered years earlier. Industry groups say more such consortiums are likely to form if interconnect costs keep rising faster than raw chip prices.

What happens next

International Semiconductor Week runs through the rest of the week in Taipei. More technical sessions are expected to detail specific interconnect standards vying to become the industry default. Whichever approach gains traction will shape how quickly AI labs can actually deploy the chips they are paying for. That includes labs racing to fund new compute capacity, like DeepSeek.

Frequently Asked Questions

What is the AI chip interconnect bottleneck?

It refers to the energy and speed limits of moving data between AI chips working together in a cluster, which industry leaders now say can consume more energy than the chips’ own computation.

What is SEMICON Taiwan 2026?

It is International Semiconductor Week’s flagship event, held in Taipei starting 31 August 2026 and drawing more than 100,000 semiconductor professionals from 65 countries.

Why does this matter for Nvidia and its rivals?

Nvidia’s roadmap depends on faster interconnect standards to support roughly $1 trillion in expected orders for its Blackwell and Vera Rubin chips through 2027.

How do US export controls factor in?

Tightening restrictions on advanced AI chips are pushing chipmakers to treat domestic manufacturing and interconnect capacity as strategically necessary, alongside new federal incentives for the compute supply chain.

Related Coverage

Sources